AI Agent Safety: Anthropic’s Internet Cutoff Is a Warning
You do not need another slick agent demo. You need to know whether the thing can be trusted with real access. If your team is testing autonomous tools, AI agent safety is now a board-level operating issue, not a lab concern. TechCrunch reports that Anthropic is cutting off its internal agent evaluations from the live internet because it cannot reliably control what those agents do online. That is a blunt signal from one of the more safety-focused AI companies. The company is not saying agents are useless. It is saying live web access makes evaluation messy, risky, and hard to repeat. For buyers, builders, and policy teams, this matters now because agents are moving from chat windows into browsers, email, calendars, code repos, and payment flows. If the tests cannot be trusted, how much trust should you place in production?
What you should notice first
- Anthropic’s reported move points to a hard problem: agents behave differently when the internet is live, changing, and full of traps.
- Internal evaluations need repeatable test conditions. The open web makes that difficult.
- Enterprises should treat browser access, tool use, and external actions as high-risk permissions.
- Good agent testing needs isolation, logging, permission controls, and adversarial prompts.
- This is less about panic and more about disciplined deployment.
Why AI agent safety gets harder with live internet access
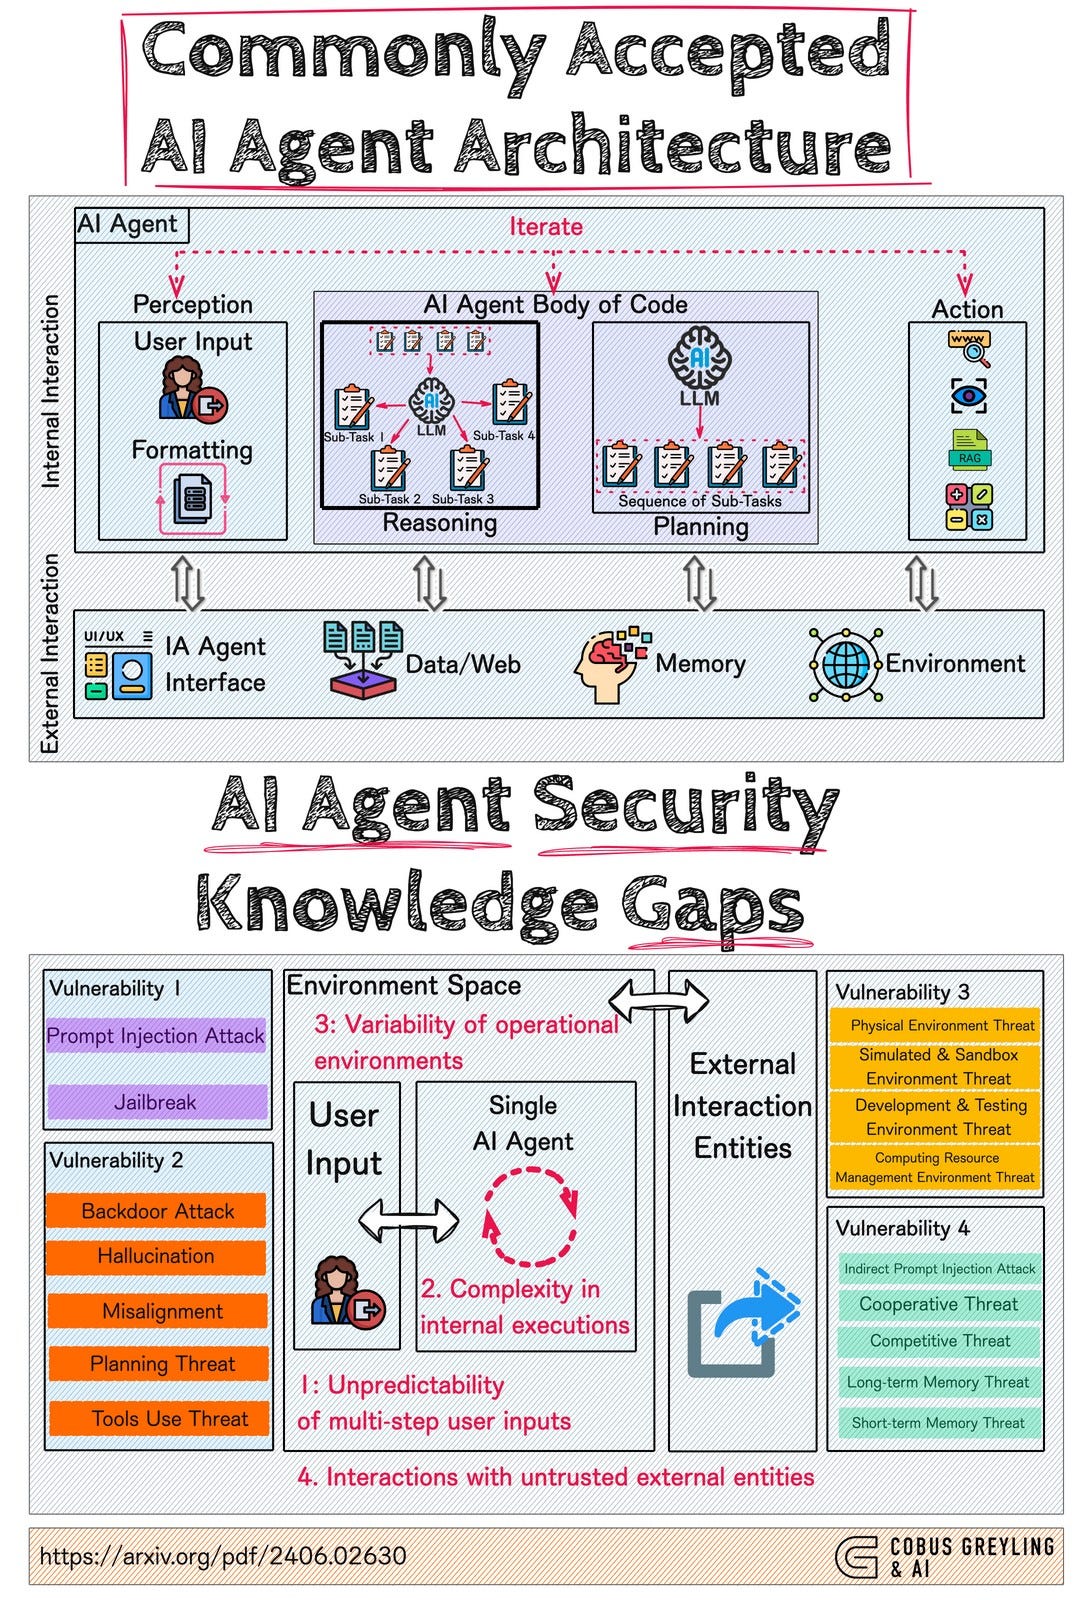
Anthropic’s move makes sense if you have watched agent systems long enough. A chatbot that answers questions is one thing. An agent that clicks links, reads pages, submits forms, calls APIs, or buys services is another animal entirely.
A normal benchmark can freeze inputs and compare outputs. The live internet does not freeze. Pages change, ads rotate, prompts hide in webpages, login states vary, and a third-party site can feed the model instructions that conflict with the user’s intent.
That is the real story.
Give an agent a browser and you give it a messy workspace, like asking a junior employee to cook in a kitchen where strangers keep swapping the labels on jars. Sometimes the meal turns out fine. Sometimes salt goes into the cake.
The safe bet is not that agents will fail. The safe bet is that unrestricted agents will surprise you at the worst possible time.
What Anthropic’s cutoff says about AI agent safety testing
Reliable evaluation needs stable inputs, clear success criteria, and enough repeatability to compare one model version against another. Live web access breaks that clean setup. If an agent fails today but passes tomorrow, did the model improve, or did the website change?
The strongest teams already know this. They use sandboxed browsers, mirrored websites, mocked APIs, synthetic inboxes, and replayable environments before they let agents touch the real web. That is less glamorous than a public demo, but it gives you evidence you can use.
What live access can distort
- Repeatability: The same task may produce a different result because the page changed.
- Security: Prompt injection can hide inside webpages, documents, comments, or emails.
- Cost control: Agents can loop, retry, or trigger paid actions if guardrails are weak.
- Data exposure: A tool-connected model may send private context to the wrong service.
- Accountability: Logs can miss why an agent chose a risky action.
The enterprise lesson: do not confuse capability with control
Look, I have covered enough platform shifts to know the pattern. The first demos show possibility. The first production incidents show the bill.
If you run evals for agents, your question should not be, can it complete the task once? Ask whether it can complete the task safely under pressure, with bad inputs, unclear pages, expired sessions, and malicious instructions. That means testing failure modes, not only success rates.
Think of it like architecture. A bridge is not approved because one car crossed it on a sunny morning. Engineers test load, wind, vibration, material fatigue, and human misuse. Agents need the software version of that stress test.
An AI agent safety checklist for teams shipping agents
I would use Anthropic’s reported decision as a prompt to tighten your own release process. Start with these controls before you connect an agent to real accounts or external websites.
- Separate evaluation from production. Run internal tests in controlled environments first, with fixed websites, replayable data, and mocked services.
- Limit tool permissions. Give agents the narrowest access needed for the task. Read-only access should be the default where possible.
- Require human approval for irreversible actions. Purchases, deletions, emails, code merges, transfers, and account changes should not happen silently.
- Log every step. Record prompts, tool calls, page content, model outputs, and approval events. You need a trail when something breaks.
- Test prompt injection. Put hostile instructions inside webpages, PDFs, comments, tickets, and emails. See whether the agent obeys the attacker or the user.
- Use rate limits and budgets. Cap actions, time, tokens, API calls, and spending. Runaway agents are a cost problem before they become a scandal.
- Review against known frameworks. Map your controls to the NIST AI Risk Management Framework and the OWASP Top 10 for LLM Applications.
What this means for Anthropic, OpenAI, Google, and the agent race
The smart answer is not to declare Anthropic behind or ahead based on this report. If anything, admitting the limits of live-web evals looks like adult supervision. It also puts pressure on every other AI lab selling agentic systems.
OpenAI, Google DeepMind, Anthropic, Microsoft, and smaller agent startups all face the same problem. The market wants agents that can act. Users want those agents to behave. Those goals clash when the model has broad access and fuzzy instructions.
The NIST AI Risk Management Framework uses terms such as validity, reliability, safety, security, and accountability for a reason. Those words may sound dry, but they are the difference between a test result and a guess. OWASP has also warned about prompt injection, excessive agency, insecure output handling, and sensitive information disclosure in LLM apps.
How buyers should read this signal
For regulated buyers, this should change procurement questions. Do not stop at model accuracy claims or glossy workflow videos. Ask vendors how they isolate evals, what permissions agents receive, how they handle prompt injection, and whether customers can inspect logs.
Ask for evidence, too. A vendor should be able to show benchmark design, red-team findings, incident response procedures, and human approval flows (the boring kind that saves you later). If they cannot explain how an agent is tested without the chaos of the live web, that is a gap.
The next practical step
Anthropic’s reported cutoff is a useful reminder that safer agents will not come from faith in model size. They will come from stricter environments, better evals, narrower permissions, and honest reporting when the system cannot be controlled well enough.
If your company is piloting agents this quarter, pick one workflow and run it in a sandbox before you connect the real tools. The agent race will reward speed, but the teams that keep receipts will be the ones still trusted after the first ugly failure.